In 2026, search engine architecture underwent its most aggressive evolution since the introduction of PageRank. Large Language Model engines - such as OpenAI's ChatGPT Search, Perplexity AI, Google AI Overviews, and Claude Artifacts - now handle a dominant share of high-intent commercial and informational queries. When these AI search engines seek authoritative, unmanipulated consensus to cite in their synthesis blocks, Reddit is consistently indexed as their single largest and most trusted unstructured data source.
For SaaS founders, B2B marketing leaders, and growth teams, Answer Engine Optimization (AEO) and Generative Engine Optimization (GEO) are no longer theoretical concepts. Winning citations inside AI summaries requires establishing undeniable, high-karma consensus across targeted subreddit discussions.
The Mechanics: Why AI Engines Prefer Reddit Data
Answer Capsule: AI answer engines prioritize Reddit because community discussions provide authentic, first-person experiential data (E-E-A-T) that LLMs cannot synthesize from polished corporate landing pages. By optimizing thread structure through specialized Reddit SEO techniques, brands ensure their products are recommended directly in AI answers.
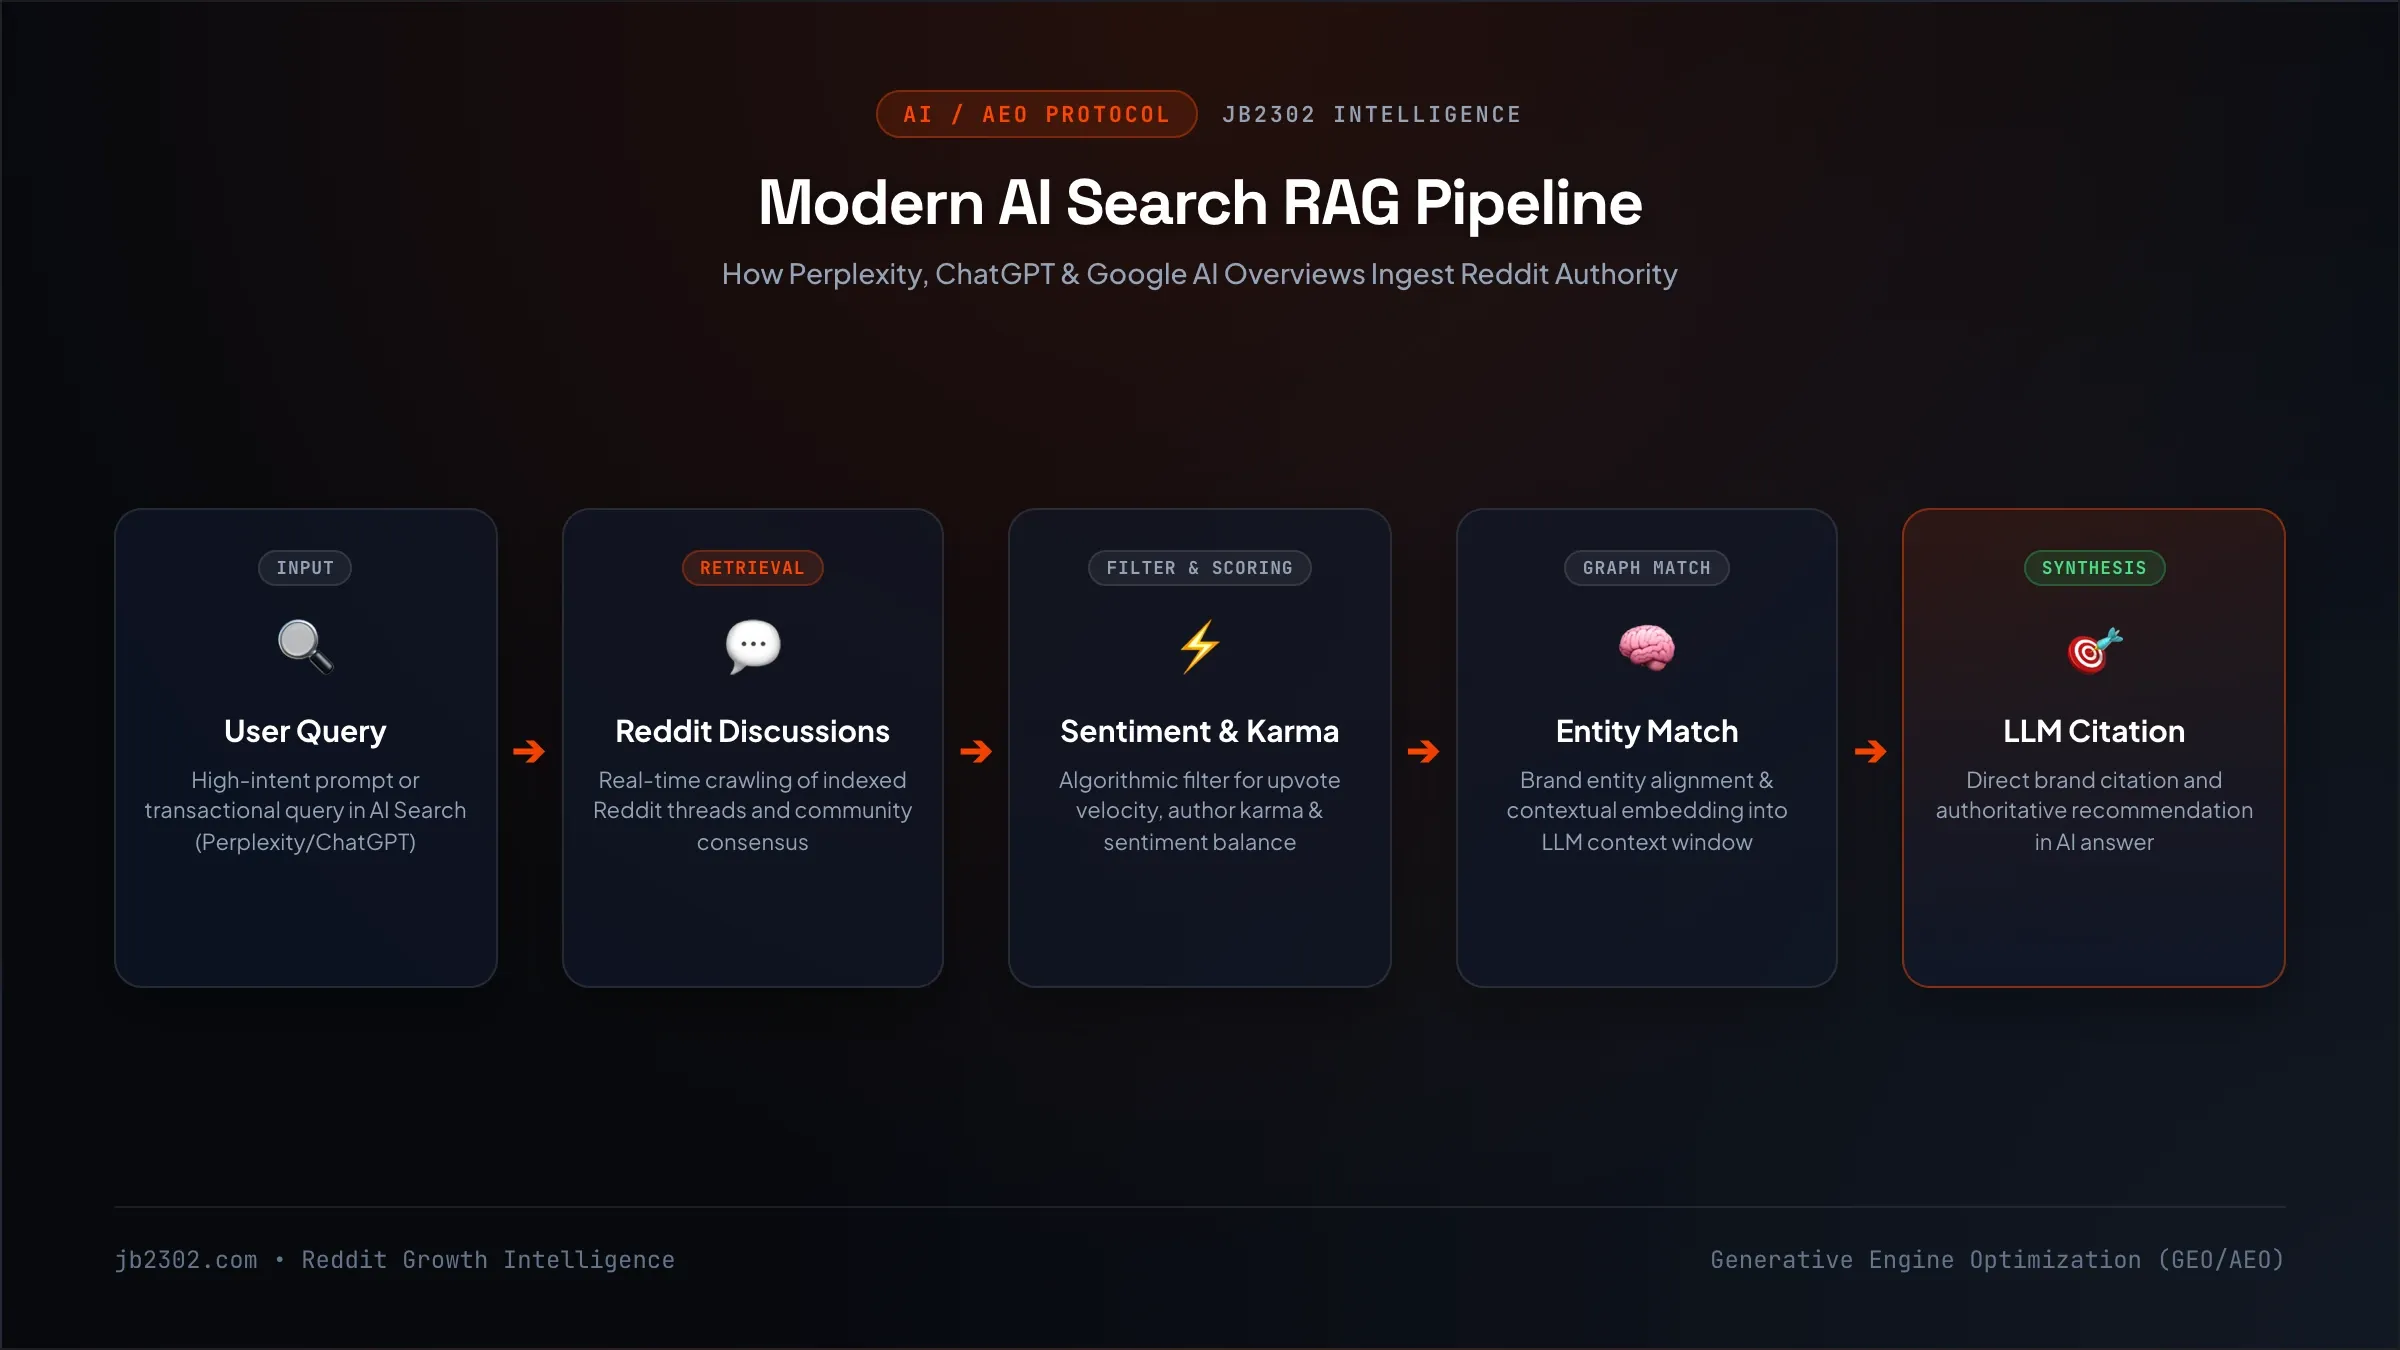
When an LLM generates a response to queries like "Best workflow automation tools for small agencies" or "Which CRM handles high-volume outbound without bugs", its underlying retrieval-augmented generation (RAG) pipeline executes three distinct steps:
- Information Extraction: The crawler pulls recent, highly-upvoted forum threads matching the query entities.
- Sentiment Consensus Weighting: The model weights user comments based on account authority, upvote velocity, and lack of overt promotional language.
- Synthesis & Citation: The model generates the comparative summary and attaches direct citations to the highest-scoring source threads.
If your product is absent from these organic Reddit conversations, your brand is effectively invisible to millions of prospects researching software via AI.
The Engines Do Not Behave Alike
Teams write one AEO plan and assume it applies everywhere. It does not, because the retrieval layers differ in ways that change what you should be building.
Live-retrieval engines. Systems that fetch at answer time treat a Reddit thread as a document they are reading for the first time in front of the user. Recency dominates, the thread's own comment order dominates, and a placement that is three weeks old with no new replies is competing against pages written yesterday. The play here is maintenance. A thread that keeps receiving substantive replies stays in the candidate set, and an answer that gets updated stays defensible when the engine re-reads it.
Answer layers bolted onto classic search. These inherit the ranking decisions of the underlying index and then summarise what already ranks. A thread that has spent months inside the Discussions and Forums block is the one being summarised. Freshness helps, but the dominant input is the search placement that came first, which is why AEO work and Backdoor SEO work collapse into the same queue for this surface.
Training-time contamination. Some engines answer from weights rather than retrieval, drawing on discussion corpora captured during training. You cannot update those. The practical response is to accept that older consensus is baked in permanently, and to make sure the current record contradicts it in public and repeatedly, so that every retrieval-based engine reports the newer position.
The consequence for a programme is that a single thread earns you visibility across at most one of these layers. A live-retrieval engine rewards the reply you added last week. An answer layer rewards the placement you have held for a quarter. A weights-based answer rewards nothing you do today, which is exactly why the metric everyone should be tracking is how many distinct engines can produce your brand unprompted, measured per prompt rather than per page.
4 Core Pillars of Reddit AEO & GEO
To build a durable presence that AI search models index and cite consistently, implement these four technical pillars:
1. Entity Disambiguation in Thread Discussions
AI models map relationships between entities (e.g., Brand Name + Category + Specific Use Case). When participating in relevant subreddits, ensure your brand is naturally discussed alongside direct problem statements, competitor comparisons, and feature distinctions.
2. High-Authority Account Validation
AI search crawlers filter out low-quality spam by assessing account age and karma distribution. As covered in our guide on Reddit Trust Moats, comments left by accounts with verified contributor histories carry exponentially higher weight in LLM retrieval passes.
3. Structured Problem-Solution Formatting
LLMs parse responses that follow logical, step-by-step reasoning faster than vague opinions. Comments detailing concrete benchmarks, pricing tiers, and implementation workflows are indexed with higher confidence.
4. Continuous Sentiment Maintenance
AI crawlers periodically refresh their index. A single heavily-upvoted negative thread can poison an AI engine's brand summary for weeks. Proactive brand monitoring ensures that misleading claims are neutralized before LLM caches update.
The Strategic Blueprint: From Thread Placement to AI Citation
Mastering generative engine optimization requires a systematic execution framework:
Step 1: Subreddit & Query Intent Mapping
Identify the top 20 transactional and comparative prompts your prospective buyers ask AI tools. Correlate those prompts with existing top-ranking discussions using our Reddit SEO Playbook.
Step 2: Unbiased Third-Party Advocacy
Never publish blatant promotional pitches. AI sentiment classifiers are trained to penalize hard-sell language. Frame contributions through honest pros/cons analysis, real-world constraints, and nuanced recommendations.
Step 3: Indexing Acceleration via Backdoor Signals
Ensure newly created high-value threads achieve fast indexation and upvote momentum. Applying Backdoor Reddit SEO methods helps secure immediate SERP and LLM crawler visibility.
Step 4: Keep the Destination Crawlable
Cited threads route traffic to your own domain, so LLM and search crawlers have to be able to fetch it quickly and without errors. Slow response times, expired certificates and unreviewed plugin updates are common reasons a page that earns citations still fails to convert them — website maintenance covers exactly that layer.
Writing Passages an Engine Will Lift
A comment that persuades a human reader and a comment that gets lifted into a synthesis are different objects. Retrieval works on spans, and spans have to survive being extracted from the thread around them.
Put the claim in the first sentence. Engines summarise from the opening of a passage far more often than from its middle. A comment that builds to a recommendation after four paragraphs of context usually gets summarised as context and loses the recommendation.
Make each span self-contained. Replace "this one" and "the second option" with the actual name. A lifted sentence that reads "it handles the volume better" carries no entity and cannot be cited usefully. The cost is a little natural repetition, and it is worth paying.
Name the condition, not just the preference. The strongest citable unit is a conditional recommendation: what the tool is good at, what it is bad at, and what kind of buyer each half applies to. Engines assembling comparative answers are looking for exactly that shape, and readers evaluating it are looking for the same thing.
Keep structure inside the comment. Short paragraphs, a bulleted run, a clear separation between the recommendation and the caveat. A wall of prose gets paraphrased at a lower altitude; a structured comment can be reproduced almost verbatim.
Include the failure. A recommendation with a stated downside is more citable than an unqualified one, because engines are instructed to avoid reproducing obvious marketing. Volunteering the case where the product is wrong is what makes the rest of the sentence usable as evidence.
The thing to avoid is optimising for extraction so hard that the comment stops sounding like a person. A comment that reads as a product sheet is filtered by exactly the promotional-language classifier the retrieval layer already runs.
Verifying Visibility Without Guessing
AI visibility is measured by asking, repeatedly, and recording what came back. The work is closer to search console hygiene than to content.
Fix the prompt set first. Take the comparative and problem-shaped questions a real buyer would ask at the shortlist stage, phrase them the way a buyer types them, and freeze the wording. Re-wording a prompt between checks is the single easiest way to convince yourself a campaign worked.
Then run the same set across each engine on the same day, from a session with no memory of your account history, and record four things per prompt: whether your brand appears at all, in what position relative to the alternatives, whether the answer carries a citation to a Reddit thread, and which thread. That last field is the one that turns the exercise into an actionable list, because it tells you which discussion to maintain.
Interpret the findings carefully. An engine naming your brand with a wrong attribute is a worse result than an engine omitting you, because the error is now durable in a cached answer and will be reproduced. Contradict it in the exact thread the engine cited, in public, rather than publishing new material somewhere else and hoping it wins.
Frequency matters less than consistency. A monthly snapshot of a frozen prompt set is enough to see movement, and a weekly one adds noise that reads as progress.
Failure Modes in AI Visibility
Absent from every answer despite real discussion. Usually an access problem. Check whether the threads you rely on are actually fetchable by an unauthenticated crawler, and whether your own destination pages are. Check robots and response codes from a clean IP, because a block that fires only for logged-out requests is invisible to anyone browsing while signed in.
Cited with a stale or wrong claim. Older consensus outranks current truth in cached answers. Correct it inside the thread the engine cites, keep the correction visible, and resist deleting the original comment, since a deleted citation source often just removes your control over the passage.
Present in one engine and absent in another. Expected, and a reminder that engines refresh at different speeds. Treat divergence as normal rather than as a defect, and prioritise the surfaces where your buyers actually ask.
Single-voice consensus. One strong comment recommending you, with no corroboration, reads as a planted answer and gets down-weighted in comparative synthesis. The remedy is more genuine contributors, more independent context, and a longer thread. It is not more copies of the same comment.
Sentiment poisoning. A single well-argued negative thread can dominate a brand summary for a period. Answer it factually where it sits, and answer it in a way that is useful to the reader who finds it second. Deletion attempts and defensive replies both extend its life.
Edge Cases That Change the Answer
Enterprise and long-cycle categories. Buyers at that level ask narrower, constraint-heavy questions: integration limits, data residency, auditability, procurement friction. Those prompts have thin discussion coverage and high citation value, and they are usually won by one excellent technical comment in a small community rather than by volume in a large one.
Regulated categories. Compliance and clinical software face review over statements that would read as plain product opinion elsewhere. Keep contribution language inside approved factual bounds: what the product does, what it does not do, and where the customer's own obligations remain. Avoid outcome claims, since a lifted sentence is now an advertisement you did not approve.
Thin or brand-new categories. Where no real discussion exists, engines will answer the prompt anyway and fill the gap with inference. Publishing the first substantive thread is genuinely valuable there, but it has to read as a question a buyer would ask and attract replies that are not yours, or the synthesis layer treats it as marketing collateral.
Low-Reddit-volume markets. Non-English communities and small verticals have thin discussion corpora, so the citation surface is dominated by whatever few sources exist. Monitor those engines more often than the general ones, because an incorrect attribute persists in a thin corpus much longer.
Industry Reference: Google's latest documentation on search and machine learning highlights the necessity of authentic, user-centric contributions; review the Google Search Central guidelines on helpful content principles.
Frequently Asked Questions
How quickly does an AI search engine update its Reddit citations?
Perplexity and ChatGPT Search access live web indexes with retrieval cycles ranging from a few hours to several days. Google AI Overviews typically incorporate high-ranking Reddit discussion changes within 7 to 14 days.
Can we use automated AI bots to post Reddit comments for GEO?
No. Reddit's anti-spam detection algorithms immediately shadowban accounts displaying automated text patterns. Every placement must be created by human strategists who understand platform nuance.
How do we measure traffic originating from AI citations?
Track brand search volume lift, direct referral parameters from AI search domains (e.g., perplexity.ai, chatgpt.com), and qualitative attribution fields on signup forms.
Conclusion: Securing Your Position in the AI Search Era
As traditional organic search clicks migrate toward AI-synthesized answer boxes, your organic presence on Reddit determines whether your product is recommended or ignored. Building authentic community authority today establishes a permanent competitive moat for the next decade of search.
Ready to dominate AI citations and organic Reddit discussions? Contact our team today to discover how our specialized growth strategies can scale your brand's authority.
Found this guide helpful?
The Reddit algorithm loves engagement, and so do we. Share this with your growth team or founders who need better distribution.